Wayfinder: Claude and GPT and Data Bridges Copy
This is the third article of six. In part 1, I explained what a data processing agreement is and why Icelandic business needs to watch carefully for changes to them.
The Broken Promise, part 3.
Andri Örvar Baldvinsson
Articles
Here I summarize the big picture: how the same models can end up in completely different places depending on the path you choose with an interactive roadmap.
As we have seen in recent months, agreements between cloud giants and model developers are starting to appear one after another, which can sometimes affect where your data ends up. What confuses some people is that Anthropic and OpenAI are both present within the environment of the cloud giants, while also offering their own API services directly or subscriptions via their own client.
There are currently thirteen available paths, and the list is not exhaustive – agreements are being added and the situation is changing rapidly. Instead of listing them all here, I will give three examples that show the spectrum, and further down in the article is an interactive roadmap where you can find your exact path. The core message is this: the same models are subject to completely different data processing agreements depending on how you connect them to your operations.
Three examples of the same models
Amazon Bedrock (Claude in AWS) within the EU Data Boundary. When you call Claude through Amazon Bedrock, the model runs within AWS in the region you select (e.g., Frankfurt or Stockholm). The data is subject to a data processing agreement with AWS (AWS DPA under European jurisdiction). Anthropic does not see your data in this setup, and it never leaves the AWS environment.
Microsoft 365 Copilot both inside and outside. Here, both OpenAI and Anthropic are Microsoft's subprocessors for different parts of the experience. Copilot is within the EU data boundary for OpenAI models (on EU/EFTA tenants), but goes outside of them (to the US) in cases where Claude handles the task. The system selects the model based on tasks, so the same product can be both inside and outside the data boundary depending on the circumstances. The agreement falls under the Microsoft DPA.
ChatGPT Plus / Free outside, and shares for training. The individual subscription (chatgpt.com and mobile apps). No European hosting available and data is stored in the US. What's more, the data is used for training by default unless turned off manually. This is the package that most employees use personally, which means work data can enter OpenAI's training processes without the company's knowledge.
Find your path
Instead of reading through all thirteen paths, you can answer three simple questions below – which model you use, how you access it, by which path, and see instantly whether it keeps data within the EU Data Boundary, who the data processor is, and under which jurisdiction it falls:
Hvar lenda gögnin þín?
Svaraðu þremur spurningum og sjáðu hvort þín leið heldur gögnunum innan EU Data Boundary.
If you prefer to see all thirteen paths side-by-side, the full table is included in parts 1 and 2, where it can be filtered by model, processor, EU Data Boundary, and jurisdiction.
Are there exceptions to data processing remaining within Europe?
The short answer is yes. All the cloud giants offer setups where data can travel, and the difference lies in what the default setting is and how aware you are of the choice.
AWS Bedrock offers the Cross-Region Inference feature as an opt-in setting. If you select a specific regional endpoint (e.g., Frankfurt), the processing does not go anywhere else. You can also select a geographic endpoint ("EU") which distributes the load between European regions (Frankfurt, Stockholm, Ireland, Paris) but keeps the data within Europe. Finally, you can select a global endpoint, which can send requests anywhere globally, but that is a choice you make yourself.
Vertex AI at Google uses a similar system with regional, multi-region, and global endpoints. A multi-region endpoint distributes the load within the EU or the US, a regional endpoint stays in one location, while a global endpoint can go anywhere, and again, you choose this yourself.
Microsoft 365 Copilot, however, uses a feature called Flex Routing, which has been turned on by default for new tenants since March 2026. It can be turned off, but the default setting allows the transfer of OpenAI processing outside the EU when load is high (Claude processing is, as mentioned before, outside the European data boundary anyway).
This is the difference in one sentence: With Bedrock and Vertex you have to choose to go outside your region, but with Microsoft you have to choose not to.
A good question to ask your service provider:
What kind of endpoints are we currently using in the cloud, and what exactly happens when the load increases with the cloud giant – does my data travel anywhere?
💡 Are you getting lost in the terminology?
If you want to better understand all these new names, acronyms, and technical concepts in AI (such as MCP, RAG, and more), I highly recommend checking out the article: Would you like some distorted data porridge?
Forgotten data bridges
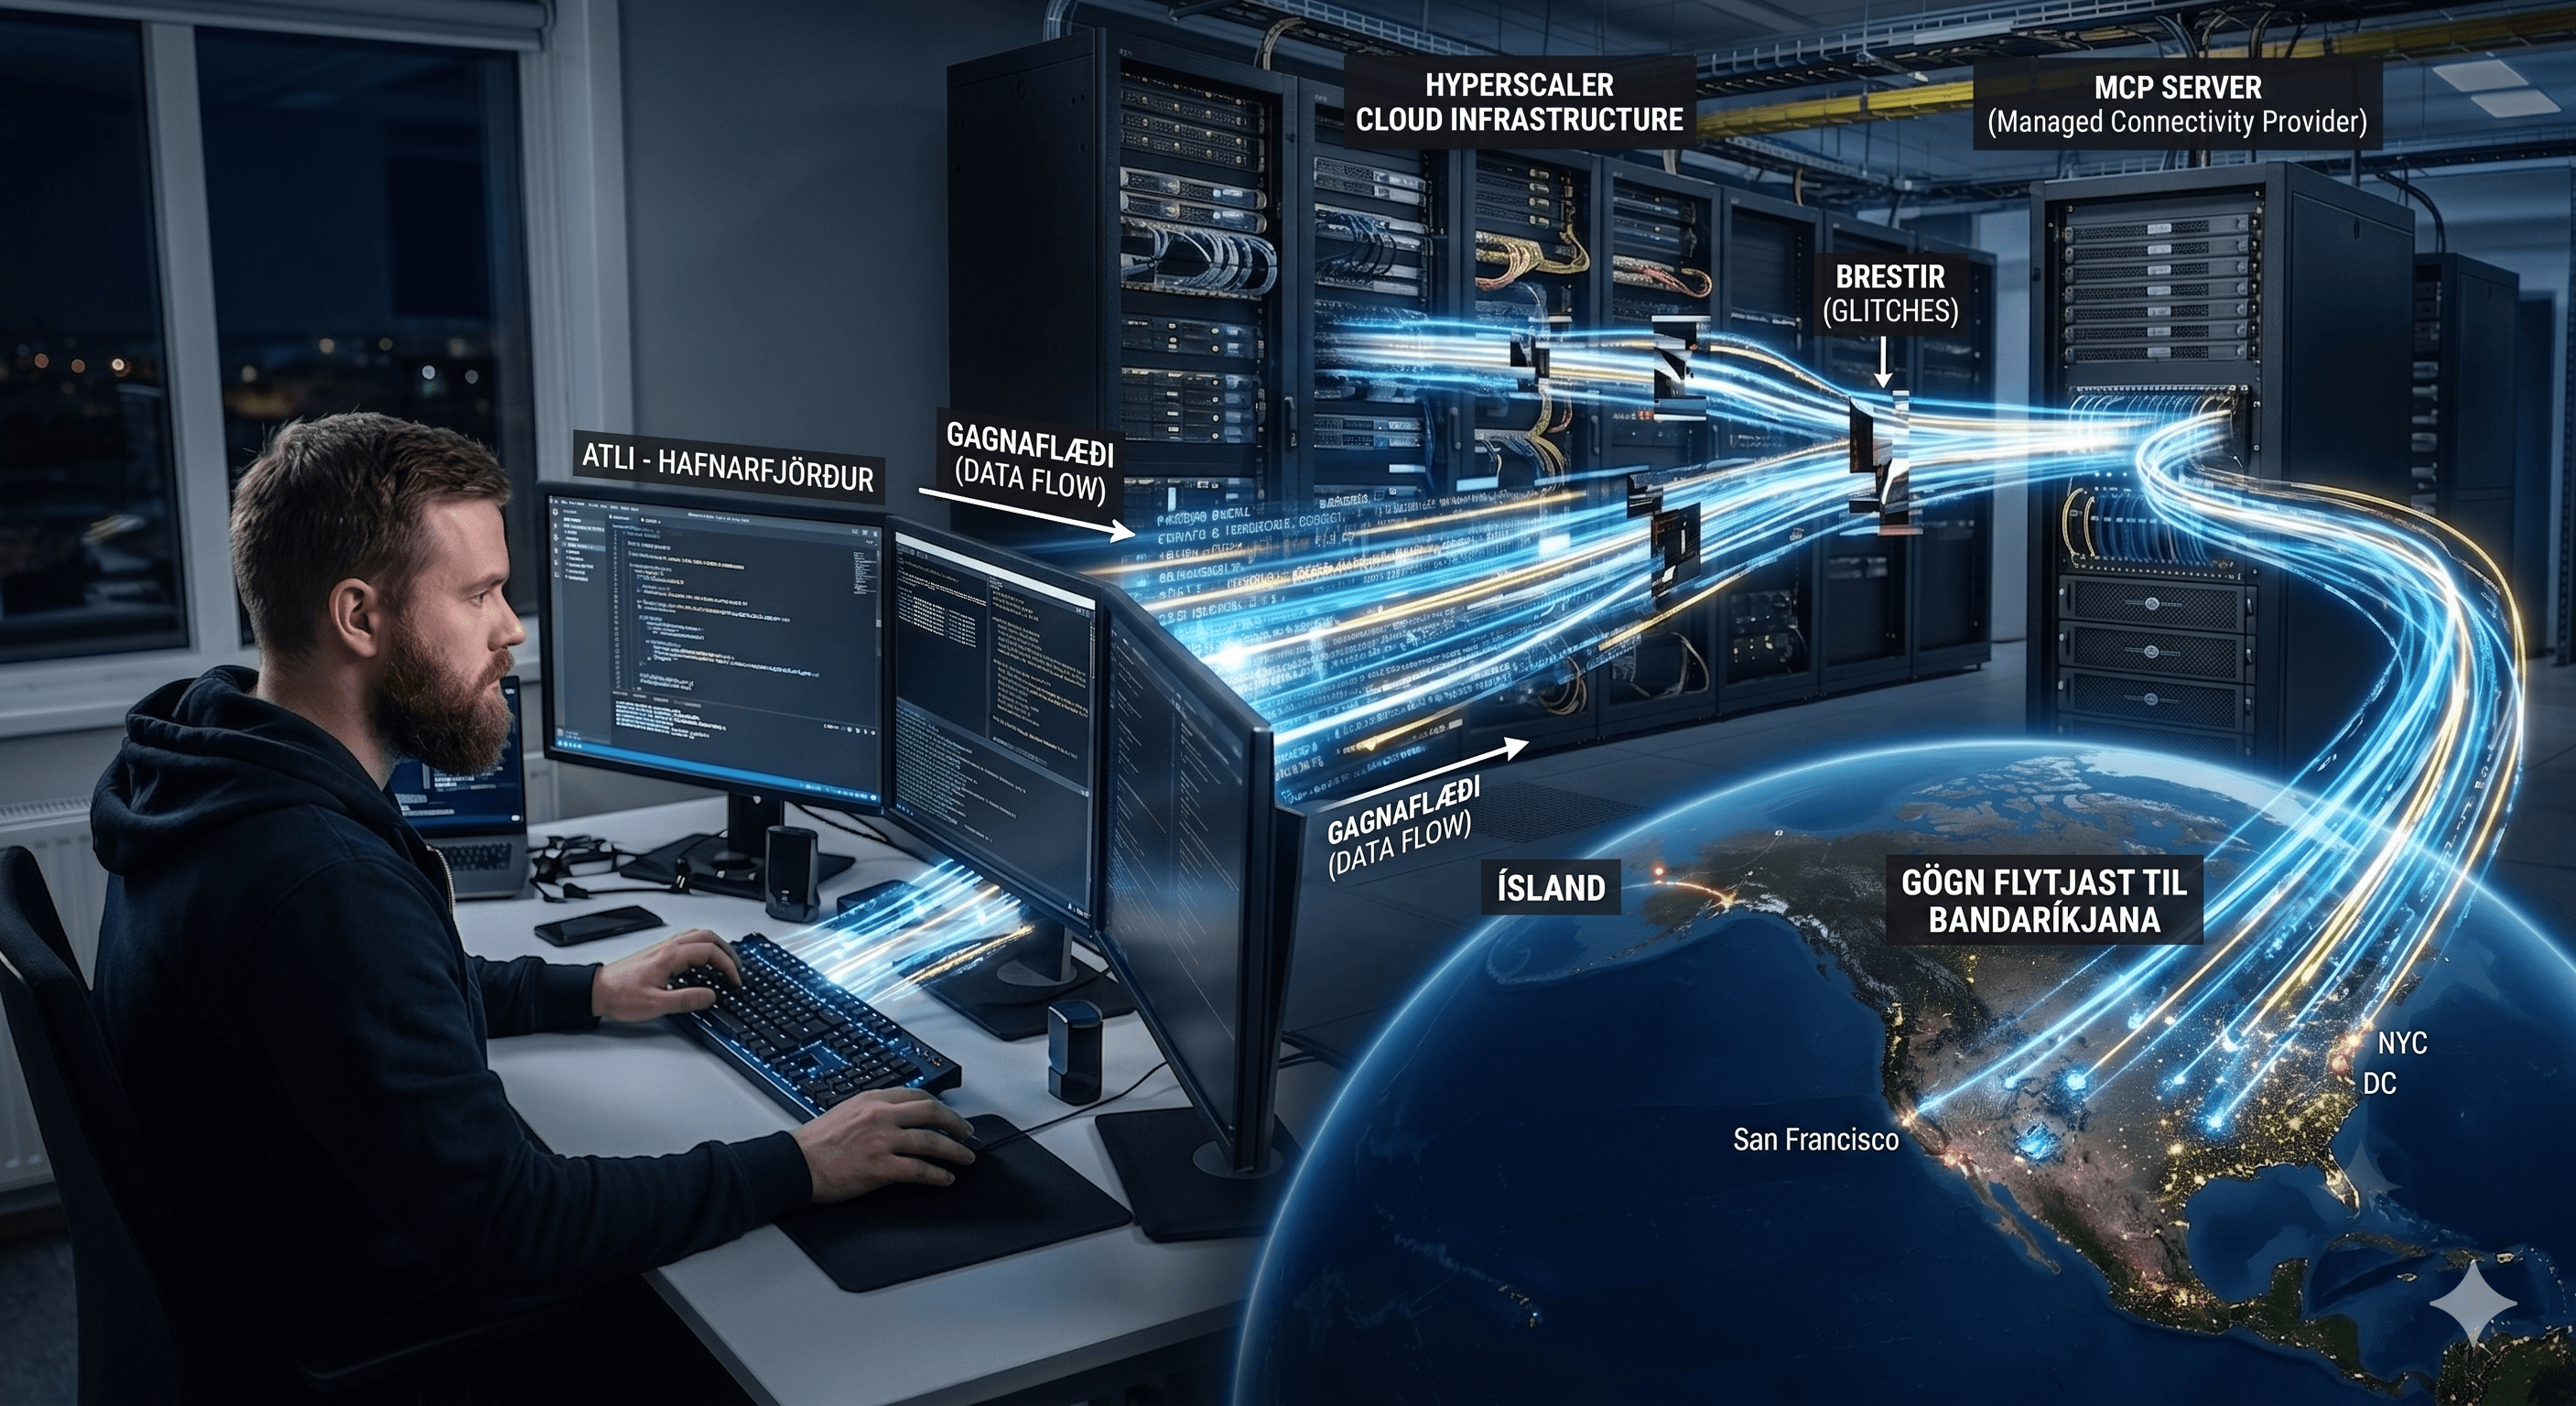
This is actually such a large topic that it warrants an entire article of its own, but I want to throw this in as a little "food for thought" for those in the know. It is of little use if the model itself is secure within Europe if the "data bridge" feeding it is leaking.
An increasing number of companies are starting to connect AI directly to internal systems (ERP systems, document archives, or proprietary software) via APIs or MCP (Model Context Protocol) services.
The technical risk: If this connection or the data bridge itself runs on a US server, the query goes there to retrieve the data before the European AI is allowed to answer. In that instant, the protection you thought you had is broken – and not by the AI itself, but due to technical architecture that might not have been sufficiently reviewed.
Changes to data processing agreements of other systems: The other side of the coin relates to the systems you are connecting the AI to. Think of giants like Atlassian (Jira and Confluence) which many Icelandic companies use on infrastructure within Europe. In August 2026, new terms take effect (Data Contribution Policy) where Atlassian will start using customer data by default to train its AI models.
The game-changer there is that if your company is on Free, Standard, or Premium subscriptions, the collection of metadata – e.g., employee search terms, project structures, and information in Confluence – is used for training. Often this is highly valuable data, and it is easy to see how this insight gives Atlassian a unique window into workflows and processes that no one else should have access to – and only those paying for the most expensive Enterprise licenses have any say in the matter.
This principle applies to all data: It does not just matter where the model is located, but where the queries go, how they travel (MCP/API), and what terms apply to the systems they touch.
What lies ahead?
In parts 1 to 3, we have covered how cloud giants operate today, where the EU Data Boundary holds and where it does not, and why the same models (Claude and GPT) can behave differently depending on the path you choose, because now it is not even enough to choose the right cloud giant or the right model developer, you also have to choose the right path within them.
In part 4, I will dive into the consequences: why this is not just a technical issue but a business decision for which the buyer must take responsibility. We will look at how a single small checkbox in settings can move your data from Frankfurt to Virginia effortlessly, and what the service provider's responsibility is in this process.
In part 5, I will address data leaks through code in software development, and in the final part 6, we will review the choice between different models and what key points need to be considered when making an implementation decision.